



Tanglis
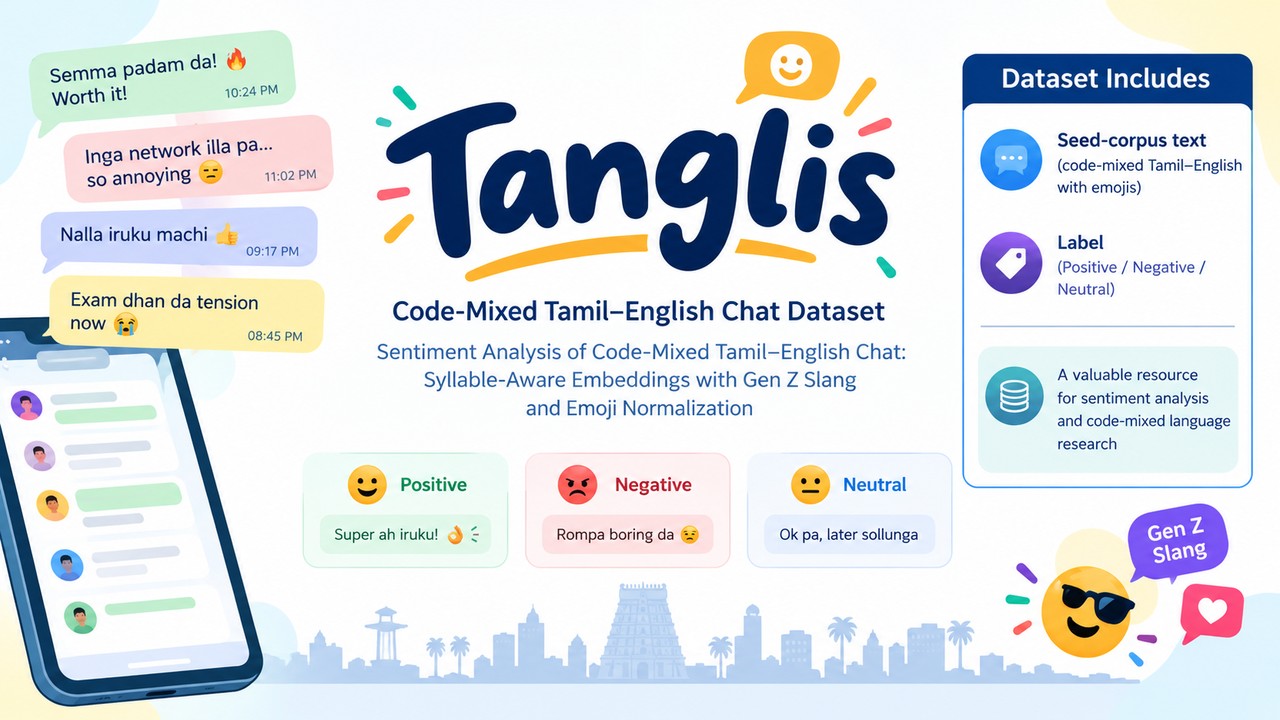
Tanglis is a code-mixed Tamil–English chat dataset developed to support sentiment analysis of informal digital conversations. It contains text messages that combine Tamil and English expressions, incorporating emojis and Gen Z slang commonly used in online communication. The dataset includes a seed corpus in which each text entry is annotated with one of three sentiment labels: Positive (pos), Negative (neg), or Neutral (neu).
About Dataset
Tanglis is a dataset designed for research on sentiment analysis in code-mixed Tamil–English chat messages. Code-mixing occurs when speakers combine words, phrases, or expressions from multiple languages within the same conversation. In informal digital communication, Tamil–English code-mixing often appears alongside transliterated Tamil, English words, regional expressions, Gen Z slang, abbreviations, and emojis. These characteristics make sentiment analysis challenging because the intended emotional meaning of a message may depend on its linguistic context, informal expressions, and emoji usage rather than on individual words alone. The Tanglis dataset contains a seed corpus of code-mixed text with emojis and sentiment annotations. Each entry is assigned one of three labels: Positive (pos): Messages expressing positive sentiment, appreciation, happiness, approval, or similar positive emotions. Negative (neg): Messages expressing dissatisfaction, frustration, disapproval, sadness, or similar negative emotions. Neutral (neu): Messages that are primarily informational or do not convey a clearly positive or negative sentiment. The dataset is intended to facilitate the study of sentiment classification in informal Tamil–English conversations. It is particularly relevant to research involving syllable-aware text representations, normalization of emojis, and the interpretation of contemporary slang. Tanglis serves as a research resource for investigating how linguistic structure and informal communication patterns influence sentiment analysis. It can support the development and evaluation of natural language processing models that aim to interpret code-mixed digital text more effectively. The dataset is associated with the research study titled “Sentiment Analysis of Code-Mixed Tamil–English Chat: Syllable-Aware Embeddings with Gen Z Slang and Emoji Normalization.
Purpose of Dataset
Tanglis is a dataset designed for research on sentiment analysis in code-mixed Tamil–English chat messages. Code-mixing occurs when speakers combine words, phrases, or expressions from multiple languages within the same conversation. In informal digital communication, Tamil–English code-mixing often appears alongside transliterated Tamil, English words, regional expressions, Gen Z slang, abbreviations, and emojis. These characteristics make sentiment analysis challenging because the intended emotional meaning of a message may depend on its linguistic context, informal expressions, and emoji usage rather than on individual words alone. The Tanglis dataset contains a seed corpus of code-mixed text with emojis and sentiment annotations. Each entry is assigned one of three labels: · Positive (pos): Messages expressing positive sentiment, appreciation, happiness, approval, or similar positive emotions. · Negative (neg): Messages expressing dissatisfaction, frustration, disapproval, sadness, or similar negative emotions. · Neutral (neu): Messages that are primarily informational or do not convey a clearly positive or negative sentiment. The dataset is intended to facilitate the study of sentiment classification in informal Tamil–English conversations. It is particularly relevant to research involving syllable-aware text representations, normalization of emojis, and the interpretation of contemporary slang. Tanglis serves as a research resource for investigating how linguistic structure and informal communication patterns influence sentiment analysis. It can support the development and evaluation of natural language processing models that aim to interpret code-mixed digital text more effectively. The dataset is associated with the research study titled “Sentiment Analysis of Code-Mixed Tamil–English Chat: Syllable-Aware Embeddings with Gen Z Slang and Emoji Normalization.”
 Dataset Metadata
ANRF Open License for Software, Models and Datasets
TamilNadu
Social
ArunKumar

Structured
Daily
NA
N.A.
19/10/26 07:47:07
Open
Hosted
Hybrid
Data Was Collected From Social Media, Messaging Platforms, Manually
 Activity Overview
 0
 0
 322.60 KB
 10
 Tags
- Tamil-English
- semantic mapping
- Sentiment Analysis
- Tamil language
- POS Tagging
 License Control
ANRF Open License for Software, Models and Datasets

Select a file to preview its contents.
 Data Quality Score Beta
 Version Control
 Version 1(322.60 KB)
- Arun Kumar· Today

tanglish_seed_corpus.csv
© 2026 - Copyright AIKosh. All rights reserved.