
Government Of India
A-
A
A+

Research Article
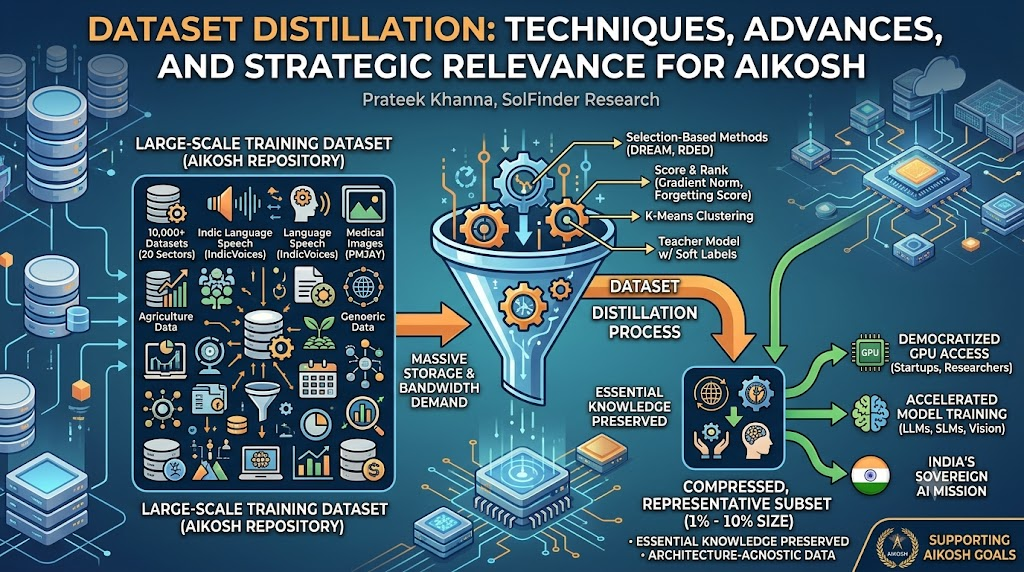
Dataset Distillation: Techniques, Advances, and Strategic Relevance for AIKosh

Dataset distillation is an emerging technique that compresses large-scale training datasets into small, informative synthetic or selected subsets while preserving the essential knowledge required for training high-performing machine learning models. This paper analyses the techniques in dataset distillation, with a particular focus on selection-based methods, and examines how these techniques can address AIKosh’s core challenges related to efficient storage, reduced computational costs, cross-architecture generalization, and democratized access to high-quality training data. The research proposes that integrating dataset distillation into AIKosh’s ecosystem can help accelerate India’s sovereign AI mission by enabling resource-constrained researchers and startups to train competitive models on compressed, representative data.
Prateek KhannaSolFinder Research
 23 Jun 2026
 2 min read
 Tags
- LLM Training
- AIkosha
- Dataset
 Activity Overview
 0
 43
Discover More Articles
 View All
© 2026 - Copyright AIKosh. All rights reserved.